 AXIOMINFERENCE
AxiomInference
The AI Lab for
local‑first
intelligence.
AxiomInference builds practical AI tools that run entirely on your own hardware, and researches small model architectures that adapt instead of just scaling. No subscriptions. No data leaving your device.
Products
All products →
Research
All research →
Project Kestrel
A 157M-parameter model trained from scratch on one GPU — hybrid attention, a looped core and sparse memory. Includes a live roadmap.
Fable-Coder
Agentic, security-aware 7B code models: four iterations, honest head-to-head benchmarks, and a 4.36 GiB build that runs on an RTX 3060.
MalxLabs-V4
A 1.5B reasoning model, fine-tuned in the cloud and tuned to run at 80+ tokens/s on a 2014-era GTX 1080.
Latest activity
All repositories →Live releases and commits from every project appear here — see them on GitHub.
Live now
Kestrel 1
Chat with a self-hosted model running on our own hardware — the same kind of endpoint Axiom's Hybrid Local mode is built to talk to.
Try Kestrel 1
What we build
One product, three research programs.
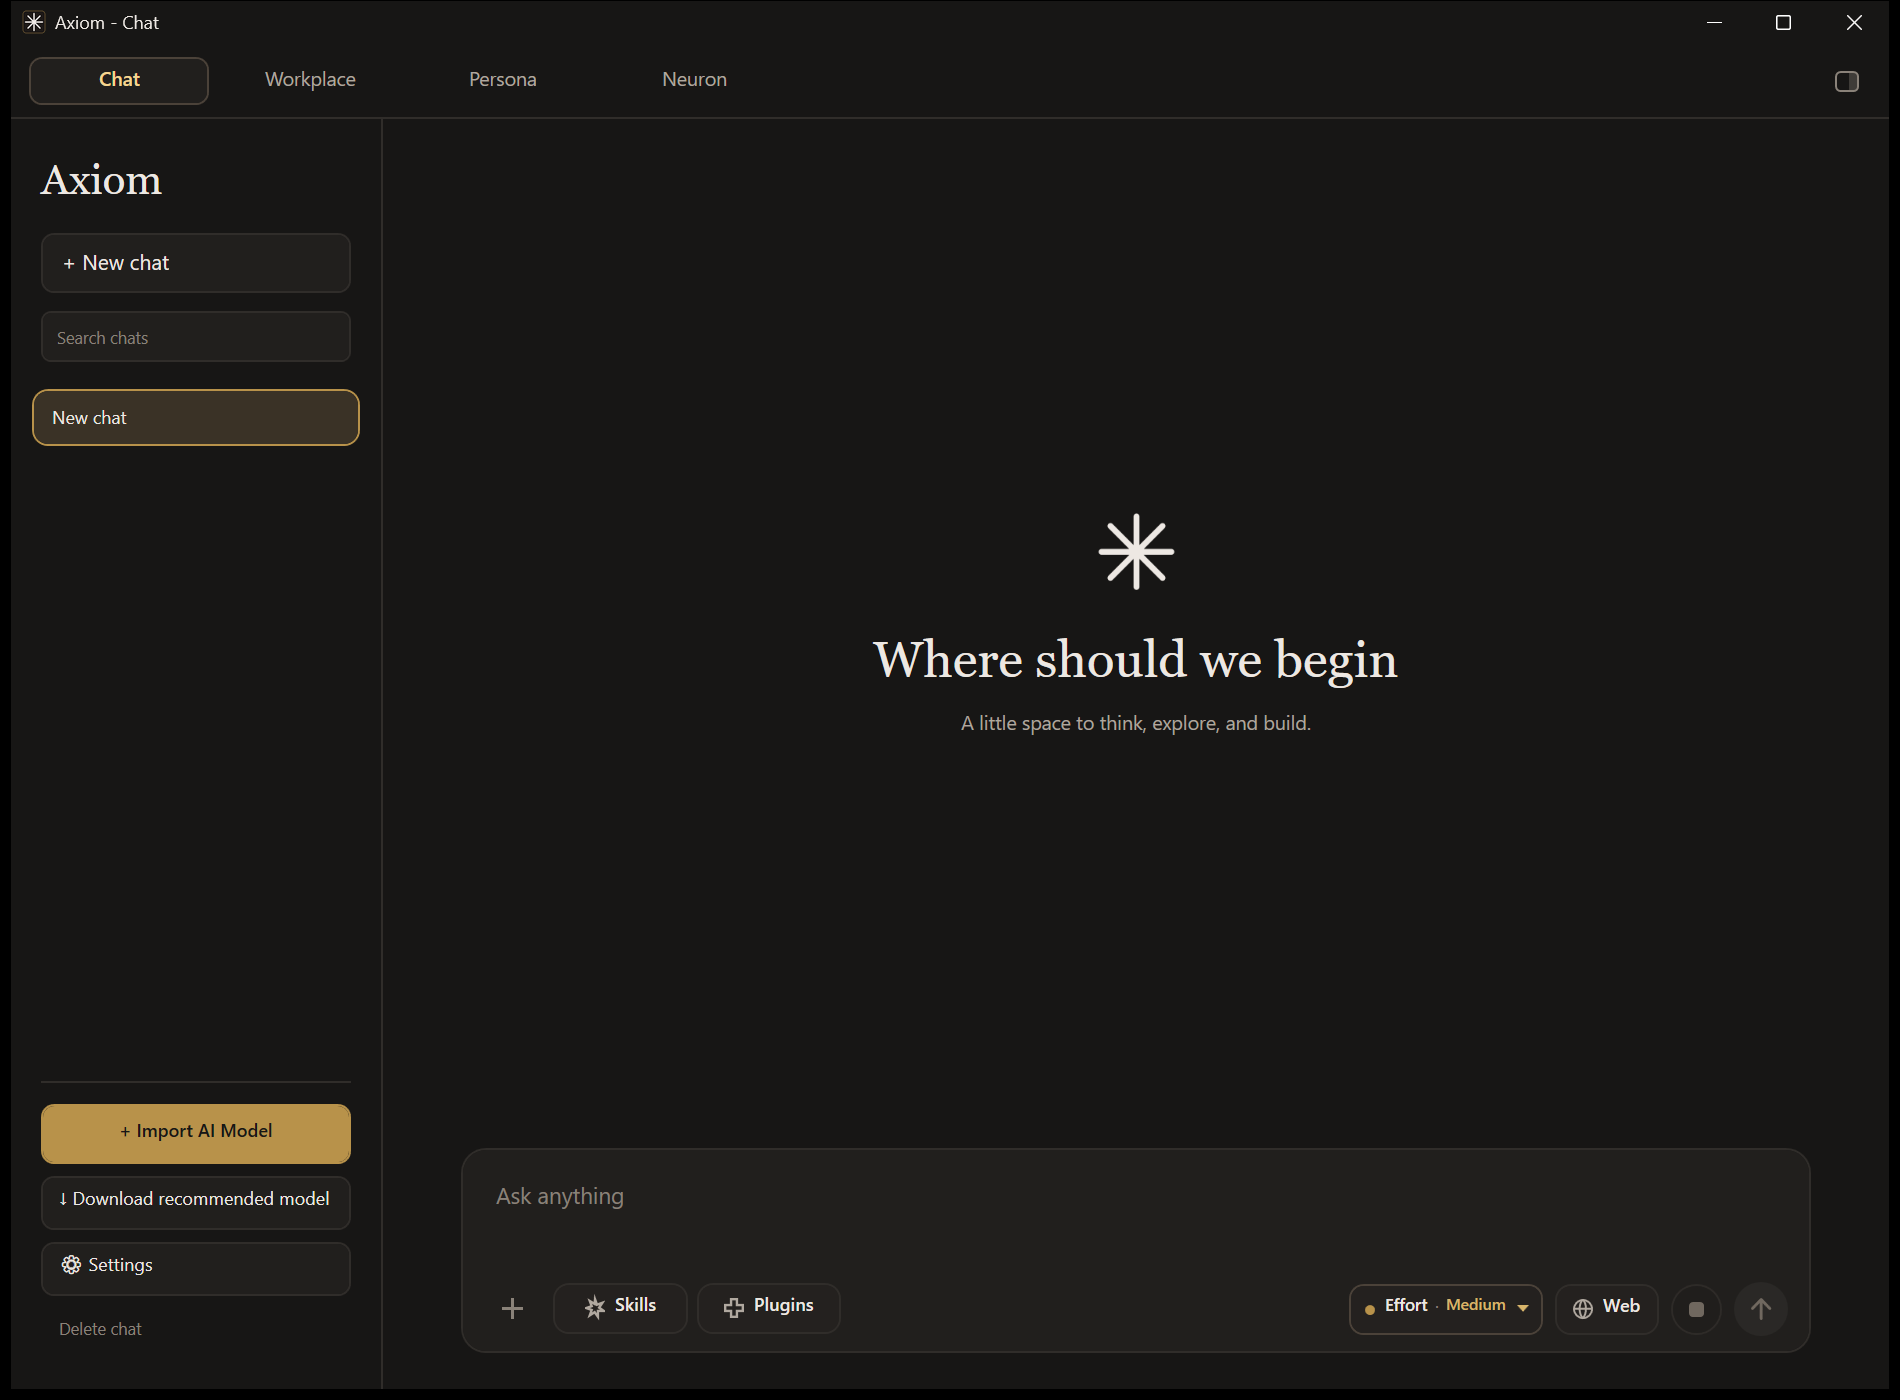
Axiom is a local-first AI workspace for Windows. It supports your own self-hosted OpenAI-compatible endpoint alongside local and optional cloud inference.
Project Kestrel is a from-scratch small-model architecture; Fable-Coder post-trains a 7B code model for agentic tool use and security; and MalxLabs-V4 tunes a 1.5B reasoner to run well on genuinely old hardware.
Why local-first
You own the hardware. You own the data.
Most AI tools send your conversations to a server. Axiom runs local GGUF models on your own machine by default, with optional cloud models when you want more power — always with your own API key, never a subscription.
Every product here also supports pointing at your own self-hosted inference server, so the same philosophy extends to hardware you run yourself, anywhere.