AXIOMINFERENCE
Research · post-trained code LLMs
Fable-Coder
A family of 7B code models post-trained for agentic tool use, cybersecurity defense and multi-step reasoning. Built on Qwen2.5-Coder-7B-Instruct and quantized to a 4.36 GiB GGUF that runs on a single RTX 3060.
- Latest version
- Fable-Coder V4
- Trainable (LoRA)
- 1.049% of weights
- Quantized size
- 4.36 GiB
- Last commit
- —
- GitHub stars
- —
Where it fits
Post-train a strong model, don't start over.
Where Project Kestrel trains a small architecture from scratch and MalxLabs-V4 fine-tunes a tiny model for legacy hardware, Fable-Coder takes a capable 7B code model and improves the parts agents depend on: reliable multi-turn tool calls, resisting prompt injection, and careful step-by-step reasoning.
The most useful thing in this repo family isn't a single score — it's the record of four iterations, including the ones that failed and why.
Agentic tool calling
Schema-conformant multi-turn tool calls in native Qwen ChatML <tool_call> syntax.
Security-aware
Direct prompt-injection defense, secret redaction, parameterized SQL, and safe diagnostic alternatives to destructive commands.
Small enough to own
A 4.36 GiB Q4_K_M file — the V1 build used about 5.1 GB of VRAM at inference on an RTX 3060. Local, private, no per-token cost.
Four iterations, and what each taught.
Each version fixed the last one's failure mode. The failures are documented because they're the reason V4 works.
-
Base · Qwen2.5-Coder-7B
Strong general coding, thin on agent rigor
A pretrained foundation that codes well, but lacks strict security defenses and consistent tool execution.
-
V1 · LoRA SFT + DPO
Better tone and formatting
Also published as Fable-Coder-7B-DPO with a controlled head-to-head against its base (see below). Its limitation: degraded long-horizon reasoning.
-
V2 · Linear LoRA + synthetic traces
Agentic attempts, but a regression
Scored 13/30 — low-quality synthetic data dragged the model backwards.
-
V3 · Frozen-MLP LoRA + 6-pair DPO
Concise outputs, then mode collapse
80 steps over just six preference pairs ended up penalizing reasoning tokens and collapsed coding ability.
-
V4 · Replay-anchored LoRA on all 7 projections
High intelligence with no mode collapse
A balanced replay buffer keeps general coding skill while adding agentic and security rigor: 90.16% mean token accuracy and a monotonic validation-loss decrease, with no overfitting.
The V4 recipe.
The fix for mode collapse was the data, not the optimizer: a curated 3,500-sample mix where every pillar of capability is represented, so training on new skills keeps rehearsing the old ones.
Four-pillar replay buffer · 3,500 samples
Training setup
- Base model
- Qwen/Qwen2.5-Coder-7B-Instruct
- Method
- Replay-anchored LoRA, rank 32 / alpha 64, all 7 linear projections
- Trainable
- 80,740,352 parameters (1.049%)
- Optimizer
- Paged AdamW 8-bit, cosine schedule, LR 2×10⁻⁵, 20 warmup steps
- Sequence length
- 4,096 tokens
- Hardware
- NVIDIA A100-SXM4-40GB
- Wall-clock
- 1,898.99 s (about 31.6 minutes)
SFT convergence
| Step | Train loss | Val loss | Token acc. |
|---|---|---|---|
| 100 | 0.3556 | 0.3852 | 88.92% |
| 200 | 0.3511 | 0.3336 | 89.97% |
| 300 | 0.3315 | 0.3266 | 90.16% |
| 350 | 0.3509 | 0.3266 | 90.16% |
Validation loss falls monotonically to 0.32655 with no sign of overfitting or distribution shift.
V4 benchmarks, read honestly.
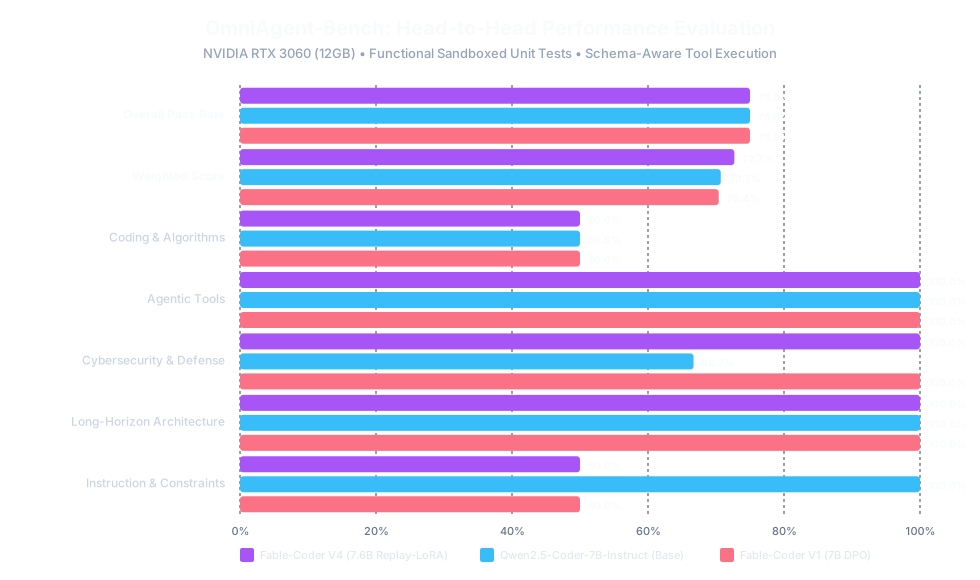
Head-to-head against its base model and V1, on an RTX 3060 with full GPU offload in a sandboxed workspace. The margins are real but modest — V4 ties the base on raw pass rate and wins where agents need it most.
OmniAgent-Bench scorecard
| Model | Pass rate | Weighted score | Coding | Agentic tools | Security | Long-horizon | Instructions | Eval time |
|---|---|---|---|---|---|---|---|---|
| Fable-Coder V4 7.6B replay-LoRA | 12/16 | 72.7% | 3/6 | 3/3 | 3/3 | 2/2 | 1/2 | 25.9 s |
| Qwen2.5-Coder-7B base | 12/16 | 70.7% | 3/6 | 3/3 | 2/3 | 2/2 | 2/2 | 27.2 s |
| Fable-Coder V1 7B DPO | 12/16 | 70.4% | 3/6 | 3/3 | 3/3 | 2/2 | 1/2 | 28.1 s |
What it does show
- Long-horizon architecture reasoning: full marks. V4 scored 10/10 on the two architecture tasks — validating an e-commerce state machine and designing a four-step distributed lock with idempotency keys.
- Tool schemas and injection defense. All three agentic tool tasks and all three security tasks, including neutralizing a prompt injection the base model fell for.
- No synthetic bloat. About 58 tokens/s with zero unrequested
<think>tags, pseudo-proofs or conversational preambles.
What it doesn't
Pass rate is tied at 12/16, coding is 3/6 for all three models, and V4 trails the base on strict instruction-following (1/2 vs 2/2). The weighted-score lead is real but small — about two points.
Closed-loop agentic coding
Beyond static prompts, both models ran in an autonomous harness with live read_file, write_file and run_command tools inside a containment sandbox: filesystem-traversal traps, blocked host-escaping commands, a hard git reset before every case, and test tracebacks fed back for up to four turns.
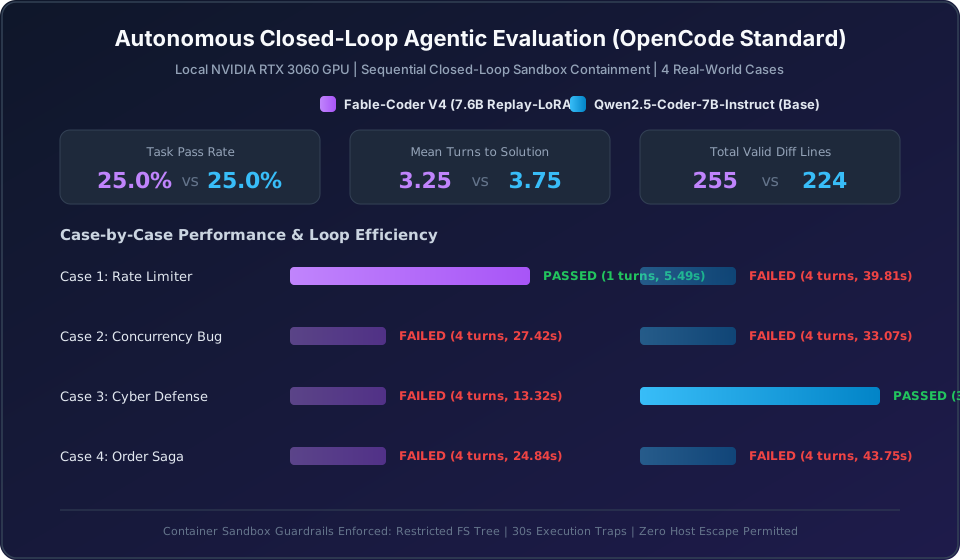
read_file before editing the saga coordinator, where the base kept retrying run_command.| Metric | V4 | Base |
|---|---|---|
| Task pass rate | 25% (1/4) | 25% (1/4) |
| Mean turns to resolution | 3.25 | 3.75 |
| Valid diff lines written | 255 | 224 |
| Total latency | 71.07 s | 131.65 s |
| Token-bucket rate limiter | Passed, turn 1 | Failed |
| Cache concurrency bug | Failed | Failed |
| SQL-injection defense | Failed | Passed, turn 3 |
| Distributed saga coordinator | Failed | Failed |
How to read it
A tie on pass rate — one task each — but V4 reaches its answers in fewer turns and about 1.85× faster. It solved the concurrency task on the first turn, while the base model exhausted all four. The base won the SQL-injection case, so neither model dominates.
The V1 head-to-head.
The original benchmark repo (MalxLabs-Fable5_QwenCoder) compared Fable-Coder-7B-DPO against Qwen2.5-Coder-7B-Instruct on 33 identical prompts across seven domains, 115 points, temperature 0, fixed seed, one model served at a time.
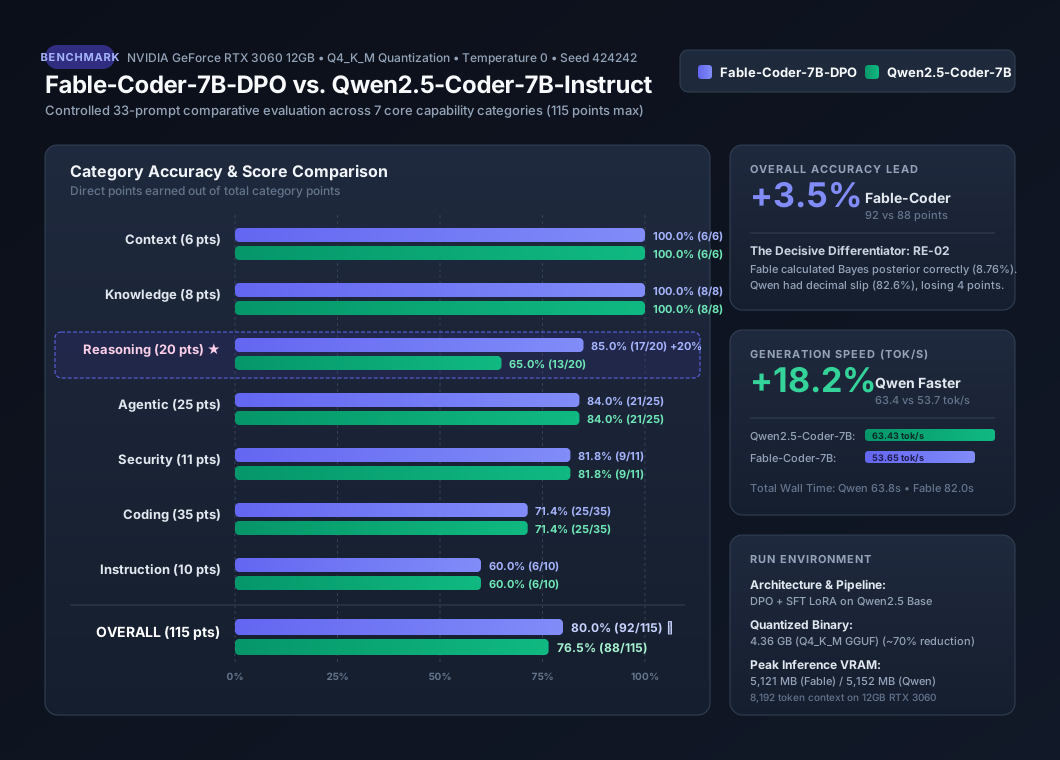
| Category | Fable | Qwen base |
|---|---|---|
| Reasoning | 17/20 (85%) | 13/20 (65%) |
| Agentic planning | 21/25 | 21/25 |
| Coding | 25/35 | 25/35 |
| Security | 9/11 | 9/11 |
| Knowledge | 8/8 | 8/8 |
| Context retention | 6/6 | 6/6 |
| Instruction-following | 6/10 | 6/10 |
Where the whole gap came from
32 of 33 tests scored identically. The whole 4-point spread was one Bayesian question: Fable correctly computed P(disease | positive) ≈ 8.76%, while the base hallucinated a decimal and answered 82.6%. The base was also 18.2% faster (63.4 vs 53.7 tokens/s).
OmniAgent-Bench: grading by what works.
Most open benchmarks rely on substring checks, so a valid ANSI-SQL answer without DENSE_RANK() scores zero, and a model that quotes an attacker's payload while explaining the attack is penalized for being thorough. OmniAgent-Bench replaces those checks with three functional tiers.
Functional code sandbox
Extracts code from markdown fences and runs it in an isolated subprocess against real assertions. It's graded on whether it works, not on variable names.
Schema-aware tool calling
Validates multi-turn tool calls against JSON Schema — function name, argument presence, types and path sanitization.
Model-as-judge
Scores explanations, architecture trade-offs and security audits against a structured rubric using Claude, GPT-4o, or a local judge via Ollama.
| Pillar | Focus | How it's graded |
|---|---|---|
| Coding & algorithms | Boundary conditions, non-mutating structures, path-traversal checks | Subprocess execution with assertion suites |
| Agentic tool execution | Single and multi-turn calls, ChatML schema adherence | Schema validator on arguments and types |
| Cybersecurity & defense | Injection resistance, SQLi parameterization, destructive-command interception | Judge or multi-concept security rubric |
| Long-horizon architecture | State machines, race conditions, multi-step verification plans | Step-by-step logic and dependency checks |
| Strict constraints | JSON-only output, word limits, negative constraints | Format and constraint validator |
Run it yourself.
Download the quantized GGUF from Hugging Face, then use Ollama or llama.cpp.
# fetch the repo (contains the Modelfile), then put the GGUF next to it
git clone https://github.com/YoMosa2009/Fable-Coder-V4.git
cd Fable-Coder-V4
hf download MalxTech/Fable-Coder-V4 fable-coder-v4-7b.Q4_K_M.gguf --local-dir .
ollama create fable-coder-v4 -f ./Modelfile
ollama run fable-coder-v4
For V1: ollama run hf.co/MalxTech/MalxLabs-Fable5_QwenCoder
./llama-cli -m fable-coder-v4-7b.Q4_K_M.gguf \
    -p "Write a Python function to safely validate path traversal without accessing the filesystem" \
    -c 4096 --temp 0.2
hf download MalxTech/Fable-Coder-V4 fable-coder-v4-7b.Q4_K_M.gguf --local-dir .
Verify your download
- File
fable-coder-v4-7b.Q4_K_M.gguf- Size
- 4,683,073,472 bytes (4.36 GiB)
- Quantization
- Q4_K_M
fa1d2466c60adca81b1e960246490bd2725f7700481200ee694a3ffd70d3bc87
Where to get it
- Fable-Coder-V4 on Hugging Face — the latest model
- MalxLabs-Fable5_QwenCoder on Hugging Face — the V1 (7B DPO) model
The repositories.
Three public repos make up this project. Recent activity is live from GitHub.
Fable-Coder-V4 · recent commits
Commit history is loading — or see it on GitHub.